VoiceStudio
Fully local voice cloning, dubbing, dictation, and transcription in one desktop app - an open-source ElevenLabs replacement.
Open source alternative to:
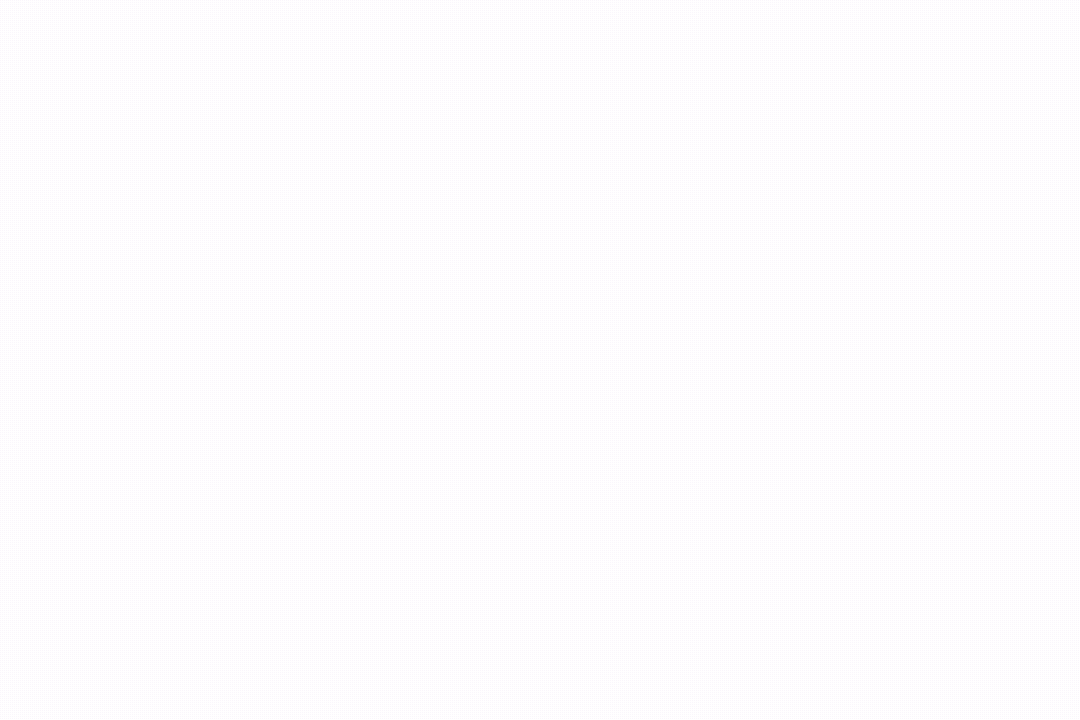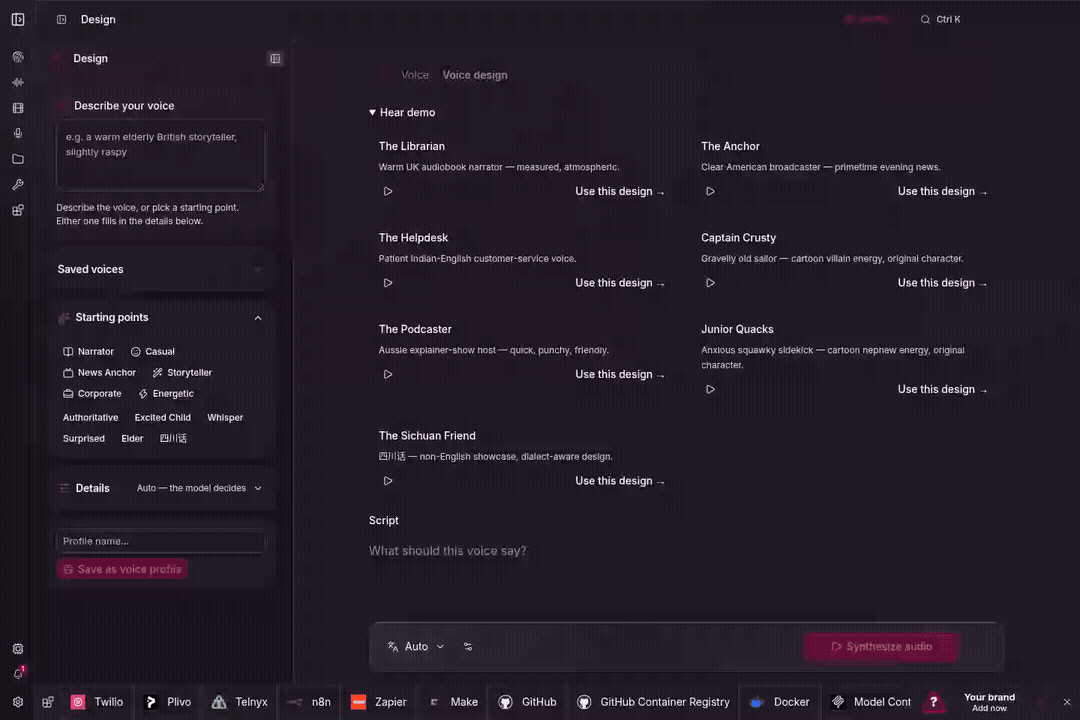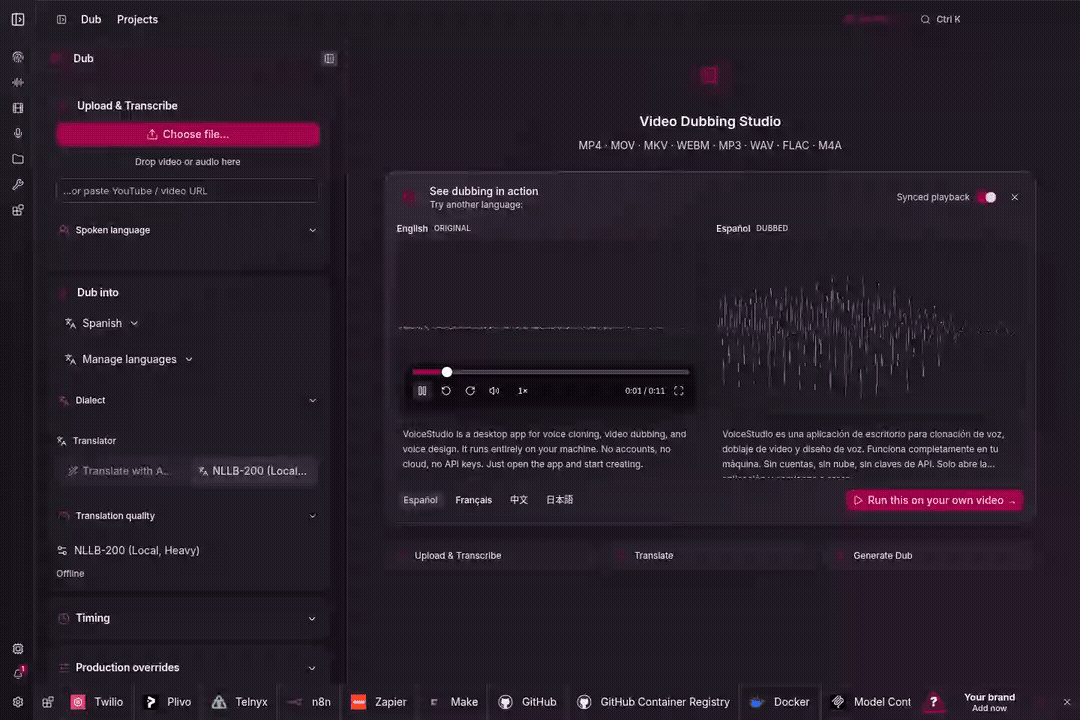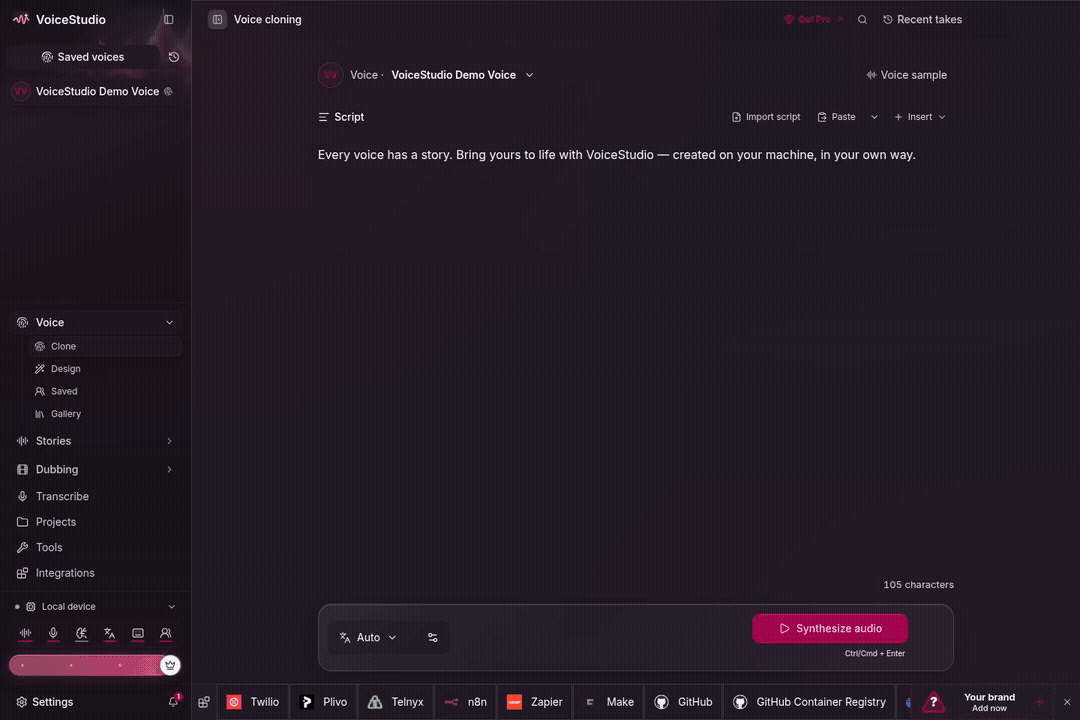
VoiceStudio is a local-first voice AI workstation that packs voice cloning, voice design, video dubbing, dictation, transcription, and audiobook creation into a single desktop app. It advertises support for 646 languages and runs all speech models on your own hardware — nothing leaves your machine unless you opt in to remote providers or analytics.
The app ships as an Electron desktop client for macOS (Apple Silicon and Intel), Windows, and Linux, with official AppImage and deb packages. For headless servers there is a Docker image (ghcr.io/debpalash/voicestudio, amd64, with ROCm variants) that serves the same UI over HTTP, so the backend can run on a GPU box while you open the interface in any browser.
Under the hood it uses a Python backend with swappable engines: speech generation defaults to k2-fsa OmniVoice with alternatives like CosyVoice 3, IndexTTS 2.5, MLX-Audio, GPT-SoVITS, and sherpa-onnx, while transcription defaults to WhisperX with Faster-Whisper, MLX Whisper, Parakeet, Moonshine, and FunASR also available. GPU auto-detect covers NVIDIA CUDA, Apple Metal/MLX, and AMD ROCm. A bundled Rust sidecar handles microphone capture and text insertion for the dictation widget.
It also works as a headless speech service: a local HTTP/WebSocket API on port 3900 plus an MCP server lets coding agents and custom apps drive dictation, TTS, and transcription. Compared to ElevenLabs, VoiceStudio trades the convenience of a hosted API for privacy, no per-character billing, and full control over which models run — cloning quality varies by the open model you choose, and heavy workloads need a decent GPU or Apple Silicon machine.
Categories:
Tags:
Build with:


Frequently Asked Questions
Which platforms does VoiceStudio run on?
VoiceStudio ships native desktop apps for macOS (Apple Silicon and Intel), Windows x64, and Linux x64 (AppImage and deb packages), installed with one command via the installer script at voicestudio.sh/install. There is no mobile app. For headless deployment there is an official Docker image, ghcr.io/debpalash/voicestudio, published for linux/amd64 only with ROCm variants.
Does VoiceStudio work completely offline?
Yes. All speech models run locally and remote services are optional. Model downloads need one-time internet access, but cloning, dubbing, dictation, and transcription afterwards run on your own hardware. Usage analytics only sends data if you explicitly opt in, and the local API binds only to loopback by default.
Can VoiceStudio be used by coding agents or other apps?
Yes. It exposes a local HTTP and WebSocket API on port 3900 and an MCP server, so tools like Claude Code, Codex, and other MCP-compatible agents can start dictation, run text-to-speech, or request transcriptions. A well-known endpoint at 127.0.0.1:3902 describes all available capabilities, and the executable accepts dictation flags from the command line.
What TTS and transcription engines can VoiceStudio use?
The default speech engine is k2-fsa OmniVoice; you can switch to CosyVoice 3, IndexTTS 2.5, MLX-Audio, GPT-SoVITS, KittenTTS, sherpa-onnx, and others. Transcription defaults to WhisperX with Faster-Whisper, MLX Whisper, PyTorch Whisper, NVIDIA Parakeet, Moonshine, FunASR, and any OpenAI-compatible server as alternatives. Engines are selected in-app per task.
What hardware does VoiceStudio need?
Requirements vary by engine, but the project benchmarks on 16 GB Apple Silicon (M2) as a baseline. NVIDIA CUDA GPUs, Apple MLX/Metal, and AMD ROCm on Linux are auto-detected. The Docker headless image is CPU-only on non-GPU machines and requires linux/amd64; Apple Silicon Macs should use the native app rather than the container for GPU acceleration.
OpenAltFinder Score
Project Details
Repository details
Compare VoiceStudio with
Similar open source alternatives
Speakr
Self-hosted AI transcription and intelligent note-taking platform that turns audio recordings into organized, searchable notes with speaker identification.
 Otter.ai
OpenScreen
Free, open-source screen recorder and video editor with polished demos, captions, zooms, and local AI editing.
 Screen Studio
Tachyon Transcripts
100% local Windows meeting transcription tool with real-time captions, speaker diarization, and offline Whisper processing.
Otter.aiOpenScreen (Archived)
The original OpenScreen screen recorder and demo creator, archived after v1.5.0.
Screen Studio
tscaps
Open-source, in-browser video editor focused on subtitles and short-form content. Transcribe with Whisper, style with CSS, export burned-in captions.
 Submagic